
Copilot Fusion Can Route Coding Work Between Local and Cloud Models in Preview
GitHub opened experimental local-model routing for Copilot Fusion on October 28. Supported setups can combine on-device models with cloud options, though routing still contacts cloud services and hardware requirements vary.
Game developers working with large codebases often face a trade-off between model speed, operating costs, privacy expectations, and the quality of difficult edits. GitHub's October 28, 2026 update to Copilot Fusion adds another option to that decision: experimental routing to local models.
GitHub says supported Copilot clients can now choose between an eligible on-device model and a cloud model as part of a single Fusion workflow. The new capability is opt-in and labeled an experimental preview. It is separate from the broader Copilot Fusion general-availability announcement made on the same date, which concerned model routing and orchestration more generally.
On supported Windows devices, GitHub describes managed installation of MAI Code 1.1 Flash through Windows ML. The Copilot CLI, Copilot app, and VS Code have their own activation steps. The CLI also offers a bring-your-own-model route using compatible local servers on Windows, macOS, and Linux, with examples including certain MAI and Qwen models.
There are important compatibility limits. A local model configured for direct selection is not necessarily eligible for Fusion's automatic routing. GitHub's announcement also states that the Copilot app's intelligent local routing currently supports managed Windows ML models, while other local-model configurations have different levels of integration.
Local execution does not make the entire session offline. GitHub explicitly says routing decisions still occur in the cloud. Developers should not advertise this feature as a way to guarantee that all prompts, metadata, or task decisions remain exclusively on the local device. Hardware memory, supported model formats, and the local inference runtime also determine whether a proposed setup is practical.
For Unreal Engine C++ development, a useful experiment might compare a small source edit against a more difficult module-dependency question. For Unity C#, a similar test could pair a simple method refactor with a task requiring awareness of engine serialization rules. Record which model handled each request when that information is available, then compare build success, answer quality, and response time.
Those tests should use a disposable project and avoid private production secrets until data flows and permissions are understood. A model that performs well on generic code may still misunderstand an engine-specific API or create a change that compiles only in the editor.
This preview is most interesting as an experiment in hybrid AI workflows, not as proof that local inference is faster, cheaper, or more private in every situation. Developers will need to evaluate whether its routing behavior and operational requirements fit their existing game-production machines.
Rate this story
What did you think of this article?
Log in to rate this story, comment and like replies.
Log inNo comments yet. Be the first to share your thoughts.
More stories
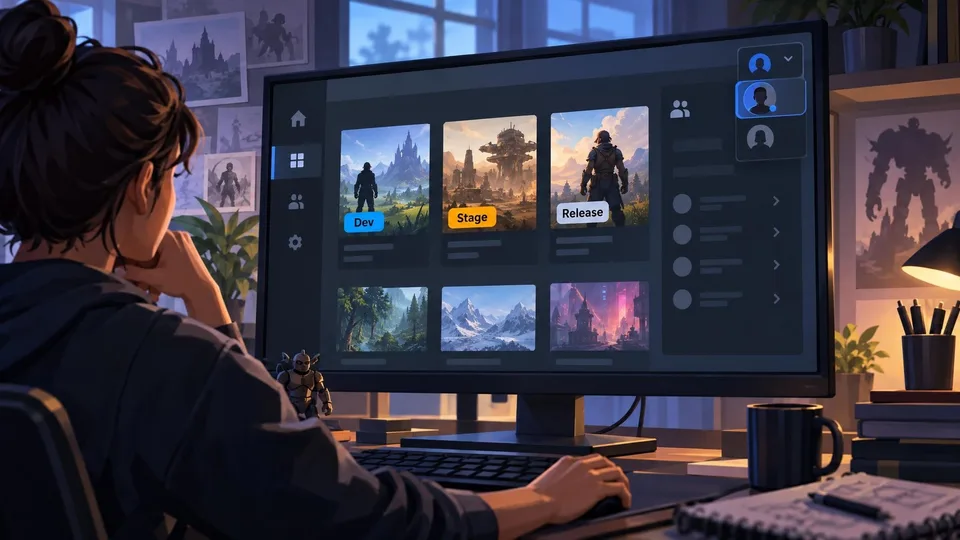
Epic Games Launcher 0.109.0 Labels Development Builds in the Library
Epic Games Launcher 0.109.0, dated November 2, adds visible Dev and Stage sandbox labels to library builds alongside account switching and a collapsible social panel. The change is about launcher workflows, not Unreal Engine rendering.
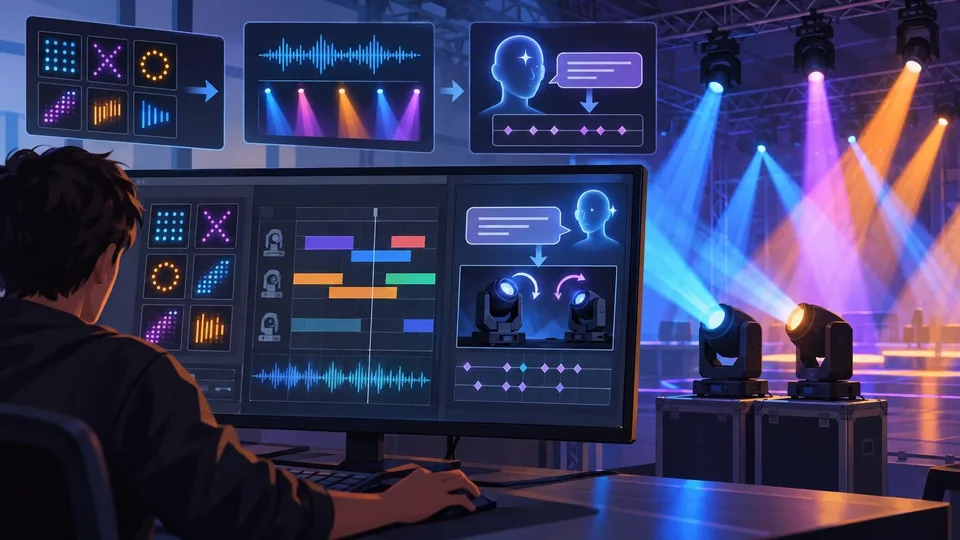
Community Unreal DMX Extension Adds Pattern Tools and AI-Assisted Lighting
An Unreal community developer described a DMX Sequencer extension on November 2 that adds reusable fixture patterns, audio-reactive animation and experimental Gemini-assisted keyframe generation. Public distribution and compatibility still need confirmation.
Netcode for Entities 7.2 Adds GameObject Bridges and Agent-Facing Unity CLI Tools
Unity Netcode for Entities 7.2.0 is listed as released October 30 with GameObject-facing networking APIs, new prediction options and Unity CLI inspection commands. It targets the Unity 6.7 beta family rather than older supported editors.
Comments